Trade secrets and AI APIs: why sensitive feeds should be classified locally
Reports of a trade secrets dispute point to a general risk: whatever goes to a third-party AI service leaves your control. Sensitive feeds should be classified locally.
Short, practical articles around the book’s topic: to read, try out and riff on.
Reports of a trade secrets dispute point to a general risk: whatever goes to a third-party AI service leaves your control. Sensitive feeds should be classified locally.
Self-hosted applications with an HTTP API can be plugged into a pipeline by polling. Using a workout tracker as an example: query incrementally, store in SQLite, notify on new entries.
Rotating tokens and passwords should not cause an outage. With two keys valid in parallel and a fixed order of steps, rotation works without interruption.
Anyone who sends many messages to one Telegram chat runs into rate limits. A queue, backoff with jitter and combining messages keep delivery stable.
A self-hosted language model through Ollama replaces the cloud API in classification: data stays in house, costs are predictable, and a fallback catches outages.
RSS and Atom can be parsed with the standard library if namespaces, missing fields and broken items are handled cleanly. An overview with example code.
A feed pipeline is easy to test when SQLite runs in memory and the language model is replaced by a stub. This is what a practical pytest strategy looks like.
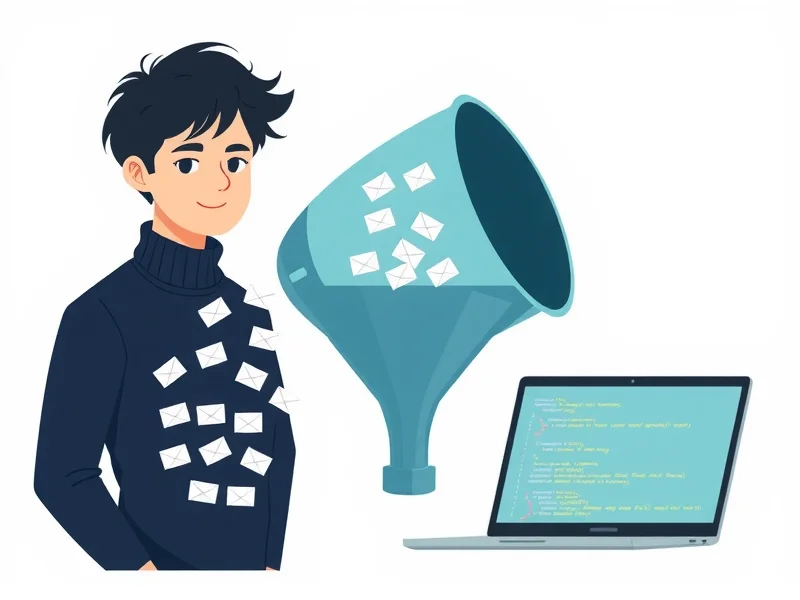
Sending every feed entry to an LLM gets expensive. Deduplication, a keyword filter, a cache and a daily budget make sure only the truly open cases reach the classifier.
Cron is quick to set up, while systemd timers add logging, catching up on missed runs and dependencies. This comparison shows which one suits a monitoring pipeline.
ntfy.sh sends push notifications through a plain HTTP call, with no bot, no token handling and no chat. Here is how to plug it into a monitoring pipeline.